The project
- Category: AI infrastructure
- Role: Design and deployment
- Period: November 2026
- Stack: vLLM, Modal, Python, fp8, speculative decoding
Open-weight models in production with OpenAI-compatible APIs
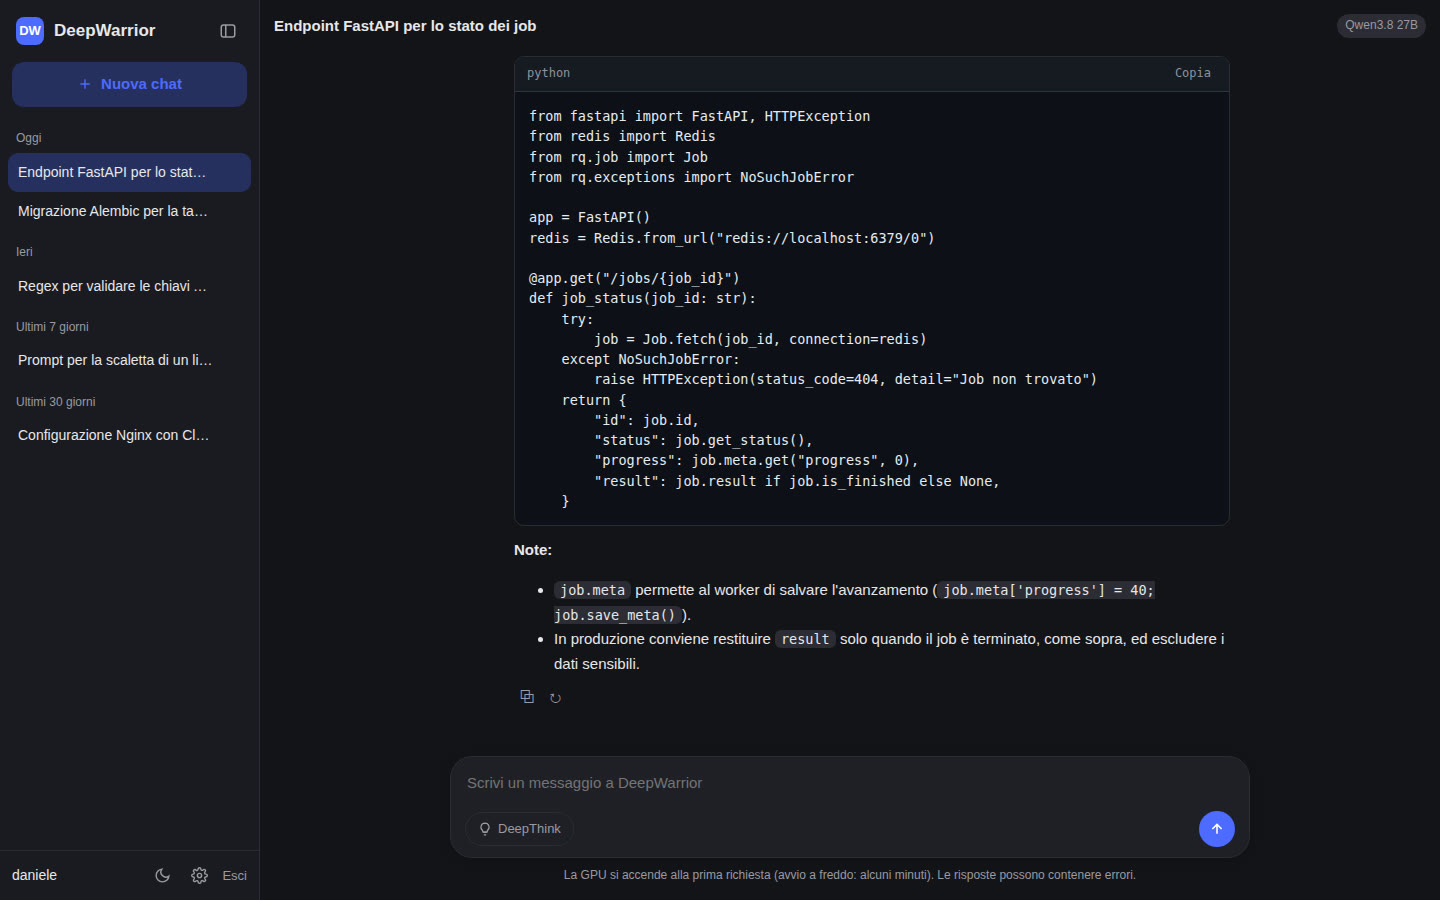
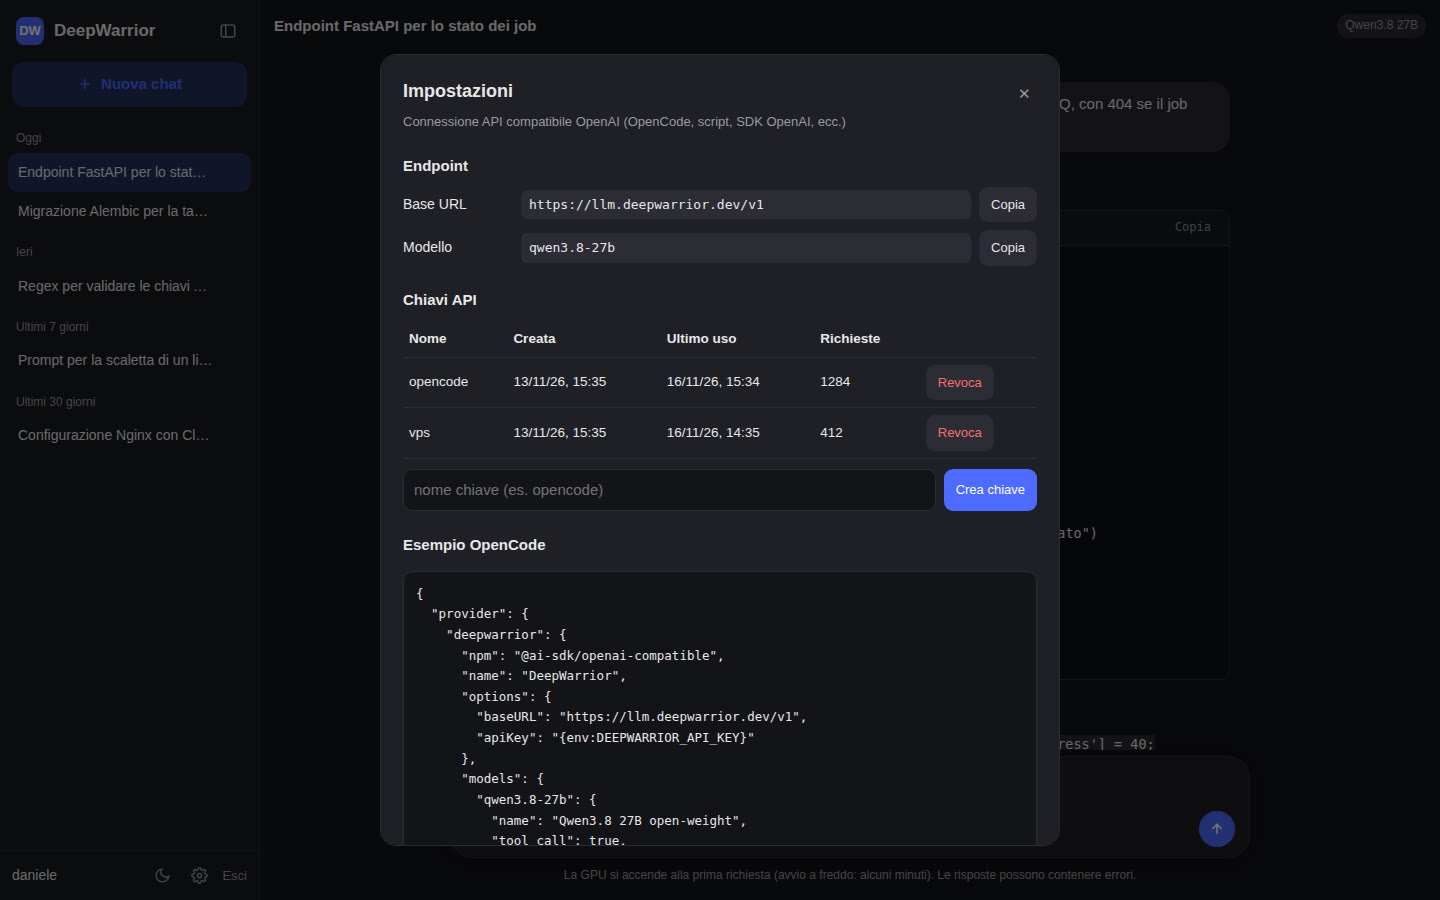
I deployed two open-weight language models, DeepSeek V4.1 Flash and Qwen3.8 27B, on cloud GPUs (Modal), exposed through OpenAI-compatible APIs and a web chat interface. The goal was to have my own models, cheap and fast, to use with development agents.
What I did
- Serving with vLLM, revocable API keys, rate limiting and a web chat interface
- GPU that shuts down automatically when idle, to keep costs low
- fp8 quantization and speculative decoding (DFlash2): about 300 tokens/s measured on H200
- Models connected to coding agents locally and on the VPS